How to Build an Agentic SEO Pipeline for SaaS Content
SaaS teams rarely struggle to generate a single draft. The harder problem is moving from an approved topic to a technically correct, on-brand, indexed page without creating a chain of manual handoffs.
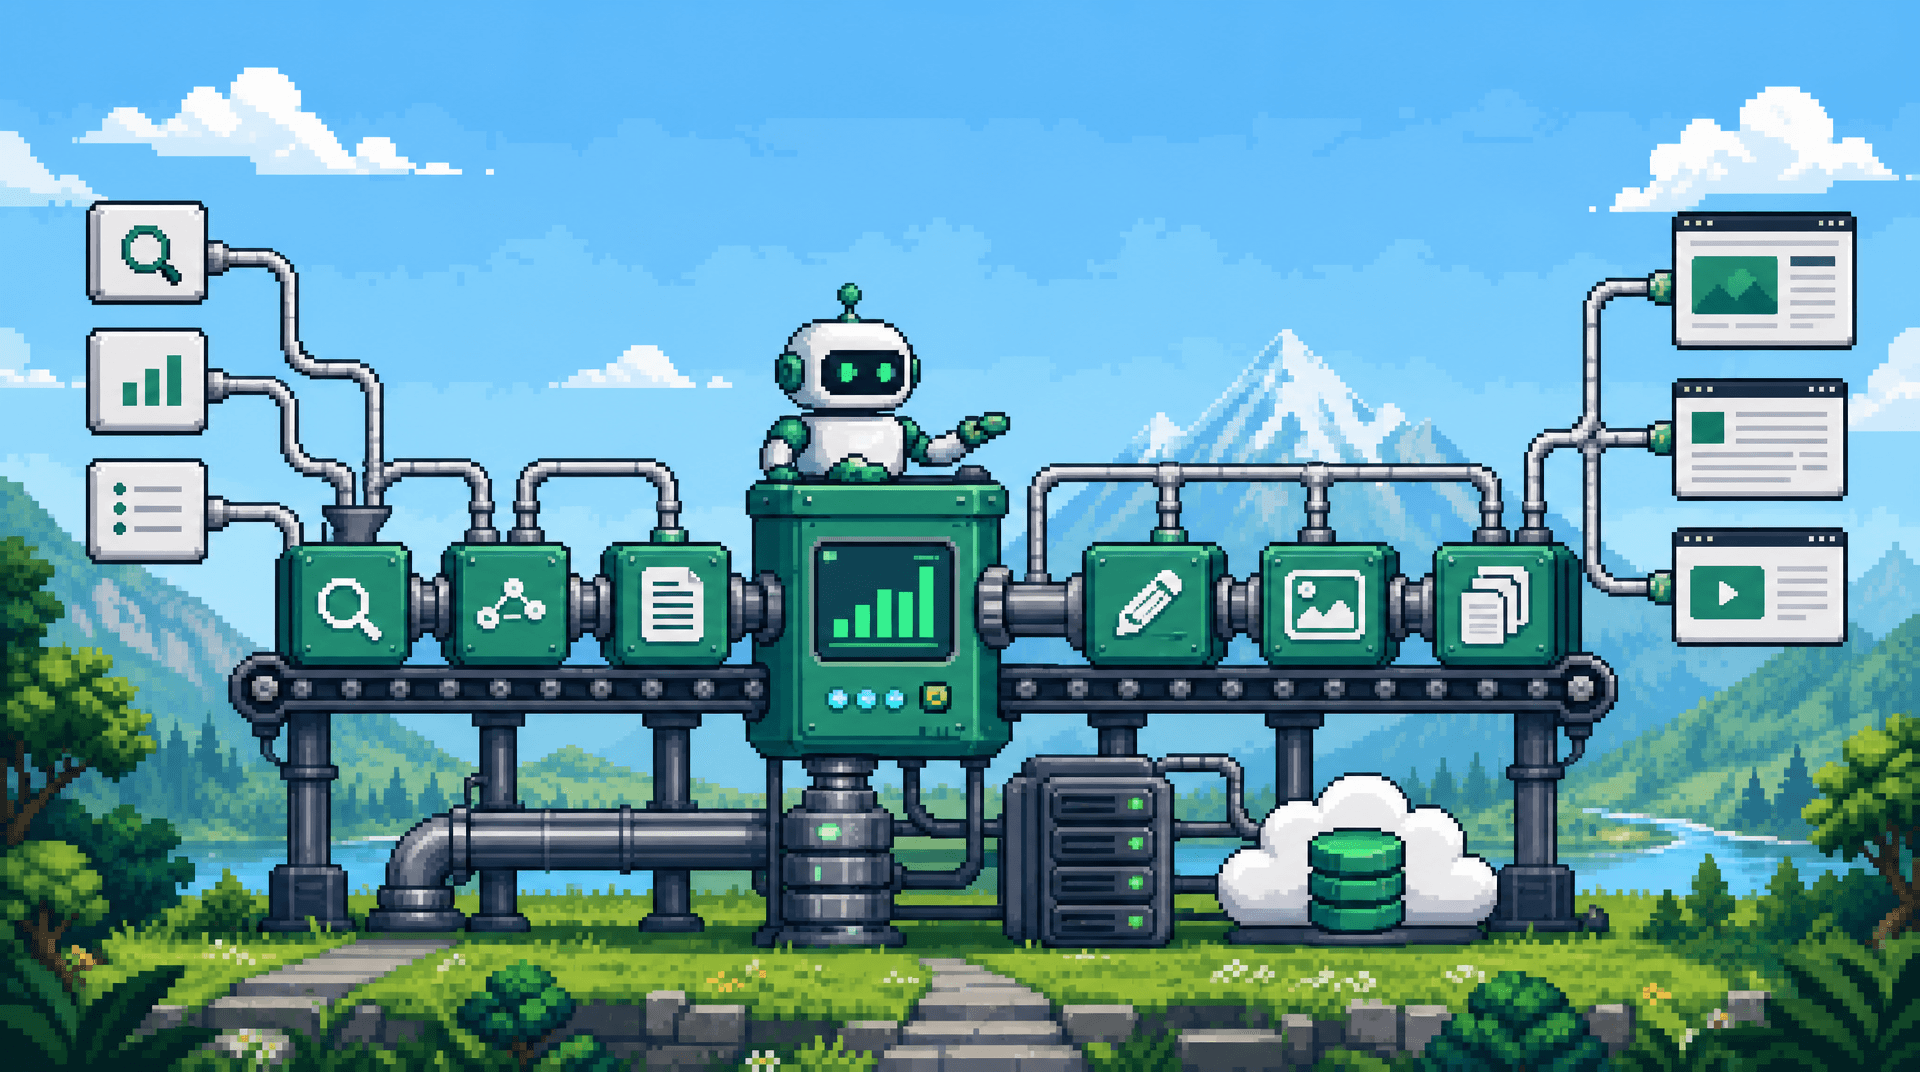
An agentic SEO pipeline connects research, product-context drafting, editorial controls, SEO metadata, structured data, publishing, and indexation into one observable workflow. This guide is for SaaS founders, growth teams, and developers who want automated blog publishing without giving up technical quality. The key takeaway: treat content as a production system with explicit inputs, validations, and release steps, not as a one-off writing task.
What an Agentic SEO Pipeline Does
An agentic workflow does more than call a language model with a keyword. It assigns bounded jobs to specialized steps, passes structured outputs between them, and evaluates whether each output is ready for the next stage. For content, those jobs may include identifying search intent, collecting product evidence, drafting an outline, generating metadata, finding internal links, and publishing a page.
The word “agentic” should not imply an unbounded system that can modify production without controls. A reliable pipeline uses deterministic rules around the generative work: required fields, allowed publishing targets, validation checks, approval states, and failure handling.
From isolated prompts to connected workflow states
A disconnected AI-generated content workflow commonly starts with a brief in one tool, a draft in another, manual edits in a document, and a copy-paste deployment into a CMS or repository. Metadata, canonical URLs, schema, images, and sitemap updates become separate chores. The result may read well but still be incomplete as a web page.
A pipeline instead creates a content record with a state such as researching, drafting, review, scheduled, published, or failed_validation. Every stage reads the same source of truth. This makes it possible to inspect why a page was published, retry only the failed stage, and prevent incomplete artifacts from reaching production.
The minimum viable content artifact
Define the page contract before choosing agents or models. At minimum, a publishable article should include a canonical slug, title, body, excerpt, primary keyword, SEO title, meta description, Open Graph data, hero image reference, internal links, JSON-LD, publication status, and timestamps.
For SSR applications, this contract should map cleanly to the fields your route or CMS renderer expects. If a required field is absent or invalid, the workflow should stop rather than publish a partially configured page.
Define the Inputs and Guardrails First
Content automation becomes fragile when inputs are informal. A seed keyword alone does not communicate the product, audience, claims policy, existing content inventory, or target route conventions. Establishing these constraints early reduces rework and helps agents produce usable outputs.
Build a product-context source of truth
Your agent needs grounded product information before it writes about your product. Crawl or maintain a curated source that includes product pages, documentation, pricing context where relevant, integration guides, customer terminology, and brand guidance. Extract claims that can be supported, feature names that must remain exact, and concepts that need technical explanation.
This is more dependable than repeatedly adding long product descriptions to prompts. Product-context crawling gives the drafting workflow current evidence while reducing the risk of generic competitor-style copy or unsupported statements.
Keep the source scoped. Exclude stale campaign pages, login experiences, private documentation, and thin tag archives. When information conflicts, designate an authoritative source, such as versioned docs or a maintained product facts file.
Set editorial and technical policies
Policies convert subjective expectations into checks. Define the audience expertise, permitted tone, target length range, heading rules, topic exclusions, citation requirements, and whether human approval is needed for particular categories. Separate style preferences from hard blocks.
Technical policy should include slug format, canonical domain, image dimensions, allowed HTML or Markdown, schema types, locale behavior, and publish windows. Also specify what the system must never infer, such as legal, security, performance, or pricing claims that lack a source.
Design the Automated SEO Pipeline Stages
A useful automated SEO pipeline has clear outputs at each stage. While implementations vary, the sequence below is practical for most SaaS content programs and supports retries without rebuilding the whole article.
Research search intent and content gaps
Start with a seed keyword, topic cluster, product URL, or competitor comparison request. The research stage should classify likely intent, identify related questions, suggest a page type, and inspect your existing inventory for cannibalization risks. It should also identify internal pages that can support the topic.
Do not blindly create a new article whenever a keyword is supplied. If an existing page already matches the intent, the correct action might be to refresh that page, add a section, strengthen internal links, or consolidate duplicates.
The research output should be structured, not just prose. For example, store the primary keyword, secondary terms, search intent, target reader, recommended angle, candidate internal links, source URLs, and a confidence or review flag.
Generate a product-grounded draft
Drafting should use the research brief plus approved product context and your content template. The system can generate an outline first, validate its coverage, then create the full draft. Separating outline generation from final writing makes it easier to catch weak structure before spending time on revisions.
Ask the writer stage to distinguish product facts from general guidance. A post about SEO automation for Next.js, for example, can explain route rendering, metadata APIs, canonical tags, and sitemap generation without claiming that a tool supports an implementation it does not support.
Use formatting constraints in the content contract: heading levels, paragraph length, table rules, code-block policy, link format, and prohibited phrases. These controls make the output easier for downstream renderers and reviewers to process.
Generate page metadata and JSON-LD schema
SEO metadata should be generated from the approved article record, not manually recreated in the CMS. Validate title and description limits, avoid duplicate canonical URLs, and require a primary keyword where your editorial policy calls for one. For SEO metadata for SSR apps, render these values in the server response so crawlers receive the page identity immediately.
JSON-LD schema generation should match the actual page. An article typically needs Article or BlogPosting markup, plus an Organization or Person publisher reference where appropriate. Include only fields you can populate accurately, such as headline, description, image, datePublished, dateModified, and canonical URL.
Schema is not a substitute for clear visible content, and it should not advertise FAQs, reviews, or how-to steps that are not present on the page. Make schema validation a required gate before publish.
Resolve automated internal linking
Automated internal linking works best when it is relevance-based and bounded. The system should retrieve candidate URLs from a site inventory, score semantic fit and page type, then choose a limited number of useful destinations. It should avoid linking repeatedly to the same page, sending users to unrelated category pages, or creating anchors that misrepresent the destination.
Require link validation before release: confirm that URLs resolve, are indexable, are not redirected unnecessarily, and use approved domains. Internal links should improve navigation for the reader first, with crawl discovery as an important secondary benefit.
Add Validation Gates Before Publishing
The difference between automated drafting and production automation is validation. Generative outputs are probabilistic, while your publishing interface, SEO requirements, and brand rules are not. Put validation between every meaningful transition.
Validate content quality and factual support
Programmatic checks can verify word count, heading hierarchy, broken links, duplicate headings, absent alt text, unsupported formatting, and required metadata. A content quality review can then focus on problems automation cannot reliably settle: whether the argument is useful, whether product context is accurate, and whether the page serves the stated intent.
Create an escalation path for uncertain claims. If the workflow cannot locate supporting source material for a product statement, it should remove the claim, flag it for review, or request evidence. This is safer than allowing confident-sounding filler into a technical article.
Validate technical release readiness
Before publication, run a release checklist against the rendered route or CMS preview. Confirm the canonical points to the final URL, Open Graph image is accessible, robots directives are intentional, JSON-LD parses, and the page works at the expected slug. For SSR, inspect the initial HTML rather than only the hydrated browser view.
The following checks separate a draft from a release-ready page.
| Check | Why it matters | Failure action |
|---|---|---|
| Canonical URL | Prevents ambiguous page identity | Block publishing |
| Title and description | Controls search snippet inputs | Regenerate or review |
| JSON-LD parsing | Keeps structured data valid | Block publishing |
| Internal link status | Avoids broken user paths | Replace invalid URLs |
| Rendered metadata | Confirms crawler-visible output | Fix route integration |
Log each result with the content version and deployment identifier. When a page fails, retry the smallest failed step, such as image generation or schema serialization, instead of rerunning research and overwriting approved editorial work.
Publish to Your CMS or Application
The destination should shape your integration design. A WordPress or Shopify workflow may publish through an API and schedule a post, while a Next.js, React, or Astro site may commit structured content to a repository, send it to a headless CMS, or create a record through an application API.
SEO automation for Next.js and React
For SEO automation for Next.js, keep the article record separate from the presentation component. A route can fetch a validated record by slug, render the body, and map its metadata fields to the framework's server-side metadata mechanism. This lets design changes happen in components without forcing content agents to understand your entire frontend.
SEO automation for React follows the same principle, with an additional concern: ensure key metadata is server-rendered or pre-rendered when organic search is important. The workflow should create canonical, Open Graph, robots, and structured-data fields as part of the record, then let your application render them consistently.
A drop-in React SDK or blog component can reduce integration time, but it should not hide the data model. Teams need access to the underlying content fields for custom layouts, analytics, localization, and future migrations.
Schedule, deploy, and preserve rollback options
Publishing is a state transition, not the end of the workflow. Use scheduled release times when editorial cadence matters, and record the page version that was released. If your site deploys from Git, treat publishing as a pull request or controlled commit where appropriate.
Keep rollback simple. Store prior versions of body content, metadata, schema, and publishing state so a bad release can be reverted without manually reconstructing the page. This is particularly important for programmatic SEO collections, where a template or rule error can affect many URLs.
Close the Loop With Indexation and Measurement
A published URL is not automatically a discovered, indexed, or useful page. The final pipeline stages should update discovery mechanisms and collect enough data to guide the next editorial decision.
Update sitemaps and request discovery
Add eligible published pages to your dynamic sitemap and update the lastmod value when a meaningful revision occurs. Submit or ping through supported search engine mechanisms when available, but do not treat a request as a guarantee of indexation. Pages still need unique value, a crawlable response, and coherent internal linking.
Exclude drafts, noindex pages, thin duplicates, and noncanonical URL variants from the sitemap. The same publishing event that changes status to published should trigger sitemap inclusion, which prevents manual drift.
Measure workflow health, not only rankings
Rankings and traffic matter, but they are lagging indicators and depend on more than your pipeline. Also measure operational signals: time from approved brief to publish, validation failure rate, percentage of pages with complete metadata, broken-link rate, and how often humans materially rewrite generated drafts.
These signals expose the bottleneck. If schema errors are frequent, improve the schema generator and validation. If editors rewrite introductions but accept technical sections, adjust the writing specification rather than increasing human review everywhere.
Key Takeaways
- Agentic SEO connects research, product context, drafting, validation, publishing, and indexation as one controlled system.
- Start with a strict content contract and grounded product sources before automating generation.
- Use validation gates for metadata, rendered SSR output, JSON-LD schema generation, links, and factual claims.
- Keep publishing integrations decoupled from presentation so your Next.js, React, CMS, or commerce stack can evolve.
- Measure pipeline reliability alongside search outcomes to improve the workflow systematically.
A dependable content engine is built from explicit states and checks, with AI doing the generative work inside a release process your team can trust.
Frequently Asked Questions
- What is agentic SEO?
- Agentic SEO uses specialized AI workflow steps to research, draft, validate, publish, and monitor SEO content. Reliable implementations add deterministic rules, approval states, and technical checks around those steps.
- Can an agentic SEO pipeline publish to Next.js?
- Yes. A pipeline can create validated structured article records, then publish them through a CMS, API, or repository workflow that a Next.js route renders with server-side metadata and JSON-LD.
- What should block automated blog publishing?
- Block publishing for missing or invalid canonicals, malformed JSON-LD, broken required links, incomplete metadata, unsupported claims, and failed rendered-page checks.
- Is programmatic SEO the same as agentic SEO?
- No. Programmatic SEO focuses on scalable page creation from structured data and templates. Agentic SEO can support programmatic SEO, but also coordinates research, validation, publishing, and indexation workflows.